Turbocharge Your QA — From User Story to Running Test Suite, Zero Complexity!
Trusted by QA teams across startups, enterprises, and agencies — from the first test case to the CI release gate.
$0To Start, on the Free Tier
7Test Types from One Story
6Test-Management Tools
3Code Exports
Built for Every Team in Your Organisation
Whether you’re a startup founder or an enterprise QA lead, QAEverest has a tailored solution that fits your workflow.
Startups
Start on the free tier and pay in credits only for what you run. One platform writes the tests, runs them on web, API and mobile, and reports on them, so a small team covers more from the first release.
Write tests from stories, repositories and browser recordings, run them with self-healing locators, and prove each check can fail with Check strength, so a green result means something was really checked.
Turn a rough requirement from Jira, Confluence, Figma or a document into a clear story with acceptance criteria. Open questions come with suggested answers, and a stakeholder can answer them from an emailed link.
See a risk score and the tests worth running on every pull request in GitHub, GitLab or Bitbucket, and generate or run tests without leaving VS Code, JetBrains, Cursor or Claude Code.
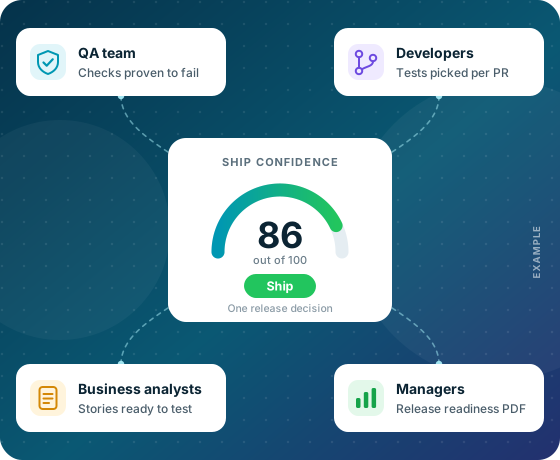
One ship-confidence score with a ship, caution or blocked verdict, requirement coverage with its gaps, UAT sign-off status, and a readiness PDF for the go / no-go meeting.
SAML single sign-on, five ready-made roles plus custom ones, an audit log and server-side tenant isolation, with Jira and ClickUp built in and a white-label programme for agencies serving several clients.
Point it at a GitHub, GitLab or Bitbucket repo of Playwright, Cypress, Selenium, pytest, JUnit or Cucumber tests and it rebuilds them as test cases, with your folders and suites. No tests yet? Source code mode reads the application itself.
Generate from a browser recording
Record a flow with the FindMyLocator Chrome extension or the Chrome DevTools Recorder, and it becomes plain-English UI steps, recorded locators included, ready to review and save to a suite.
Update a changed story’s test cases in the same record. Each one is marked New, Changed, Unchanged or Possibly obsolete for you to accept or reject, and the earlier version can be restored.
02Trust
A green result you can believe
Never trust a test you have never seen fail. These show which checks really catch a wrong answer, and which only look green.
Changes the expected value of every check that passed and judges it again against the stored run. A good check now fails; one that still passes is flagged with a hint. Nothing is sent to your app and no credits are used.
No pass without a check
A web UI test whose steps all worked but whose checks could not be confirmed is marked Not verified, with the reason, instead of passing quietly.
Test Case Audit
A free audit with no AI involved: exact duplicates, data variants, generated cases never automated, and automated tests with no test case behind them.
03Ship
The right tests for every pull request
Run what a change can break instead of the whole regression suite, with the risk and the picked tests shown on the pull request itself.
Example
#482 Rename the checkout route
Risk7 / 10
Checkout as a guest
Checkout with a saved card
Order history link
QAEverest / Smart Selection — passed
PR bot settings are in Beta, and every option starts off.
Comments on each pull request, or merge request on GitLab, with a risk score out of 10 and the tests worth running, and keeps that comment current on later pushes.
Pull request checks
On every push the bot runs the tests it picked and reports back as a “QAEverest / Smart Selection” commit status, passed or failed, with a link to each run.
Fixes for tests a change breaks
When a GitHub pull request renames a route, on-screen text or element id that a test uses, it proposes the step edits, and after the merge it checks the suites the change touched. Nothing changes until a person accepts.
04Go further
Testing beyond the scripted path
Let an agent explore your app, test your own AI features, and check the database behind an API call, while your team decides what matters.
Example
Flow passedBug foundNot crawledNew since last crawl
Give it a URL and a login. It crawls, maps every page it reaches, runs realistic flows and drafts a bug for each failure. Re-crawl after a release to see new, changed and removed pages, and save the passing flows as a UI suite.
AI agent and LLM testing
Test your own chatbot or agent through the HTTP endpoint it already has, with factual, refusal, tool-call, personal-data and red-team scenarios, then gate releases on it from GitHub Actions or any pipeline.
Mobile runs on BrowserStack, Sauce Labs or LambdaTest
Parallel web runs
Localization testing
Shadow DOM, SVG icons and iframes
Figma design import
AI Copilot
Traceability and coverage gaps
UAT cycles and sign-off
Quality Command Center
Playwright, Selenium and Cypress export
IDE plugins and MCP server
Push to six test-management tools
Jira and ClickUp bug filing
Slack and email reports
Reports Your Managers Can Act On
Your QA team runs the tests. QAEverest turns the results into short reports for the people who make the release call — each one answers a single question.
Release Readiness
Can we release this build?
A recommendation, what must be fixed first, and the risks of releasing now — all on page one.
PDF
Open Failures
What is still broken, and how serious is it?
Every open failure, worst first, with counts by severity.
PDF
Requirement Coverage
Which requirements have no test yet?
Every requirement grouped by module, with its tests and UAT status.
PDFExcel
UAT Cycle & Sign-off
Have the business users signed off?
Cycle progress, failed and pending cases, and the sign-off record.
PDFExcel
Integration (SIT) by Area
Which parts of the system are not ready?
Passed, failed and not-run cases for each area, plus contract failures.
PDFExcel
Scan Trends
Are performance, security and accessibility improving?
Each target’s latest result and how it has changed over time.
PDFExcel
Every report is built from your own test runs. It recommends; your release owner decides.
Enter your testers, QA salary, regression cycles, suite size, and release frequency — and see the hours, cost, and release time QAEverest gives back in year one.
Detailed breakdowns across cost, speed, accuracy, and capability — so you can see exactly what changes when your team adopts QAEverest.
01QAEverest vs Traditional Testing Process
Unlock the Power of AI Testing: QAEverest vs Traditional Process
See how AI-driven testing replaces costly, slow manual workflows — from test case generation to delivery, execution, and export.
Comparison of QAEverest AI testing tool versus traditional manual testing process
Feature
QAEverest
Traditional Process
Test Case Generation
AI writes complete test cases — steps, data and expected results — from a story, a Jira or ClickUp issue, a Figma design, a document, a repository, a pull request or a browser recording.
Manual creation — a skilled tester produces roughly 20 test cases per day.
Test Case Types
Seven types from the same story — Functional, System, API, Integration, Database, Security and Performance — plus an optional pairwise set that covers every pair of option values.
Typically one type per session; Security and Performance are rarely prioritised.
BDD / Gherkin Support
Full Given–When–Then scenario generation alongside traditional TDD format.
Requires a separate BDD framework and significant manual scripting.
Download & Export Formats
Excel or CSV download, a direct push to Zephyr Scale, TestRail, qTest, Qase, Azure Test Plans or PractiTest, and runnable Playwright, Selenium or Cypress code after a run.
Stored in spreadsheets or documents; format conversion is manual and error-prone.
Story Refinement
AI clarifies vague user stories, detects missing scenarios, and refines requirements before a single test case is written.
Requires lengthy BA workshops; gaps typically surface only during test execution.
Existing Tests & Recordings
Imports a repository of Playwright, Cypress, Selenium, pytest, JUnit or Cucumber tests, or a browser recording, and rebuilds it as readable test cases and suites.
Moving to a new tool means rewriting every existing test by hand.
API Automation
Built-in API engine: suites from a Postman collection or Swagger spec, chained requests that pass values on, field-by-field response checks, and read-only database checks against PostgreSQL, MySQL/MariaDB or MongoDB.
Requires a separate framework (Postman, RestAssured); all setup and maintenance is manual.
UI Automation
Built-in cross-browser automation with self-healing locators (Shadow DOM, SVG icons and iframes included), parallel runs, locale / timezone / device emulation, video recording, screenshots, and consolidated dashboards.
Requires a separate framework (Selenium, Playwright); setup, maintenance, and licences add significant cost.
Mobile Automation
Android and iOS apps through Appium, on real handsets or on BrowserStack, Sauce Labs and LambdaTest, with scheduled runs and the same reports as web.
Separate tooling (Appium, Espresso) with its own scripts, runners and reports.
Visual Regression Detection
Every passing step’s screenshot becomes its baseline, and later runs show a highlighted diff — kept per browser, emulated device and data row.
Manual visual review only; no systematic baseline tracking or automated comparison.
Time-Travel Replay
Replay any run frame by frame with console, network and page detail; for a failed web UI step, AI compares the screenshots and names the likely cause.
No replay — the entire test must be re-run from scratch to investigate a failure.
Trust in a Green Result
Check strength proves each check can fail, and a web UI test whose checks could not be confirmed is marked Not verified instead of passing.
A passing test is assumed to check something; weak checks go unnoticed until a bug slips through.
Pull Requests & CI
A risk score and the tests worth running on every GitHub, GitLab or Bitbucket pull request, run as a commit-status check; scheduled runs and pipeline triggers too.
The full regression suite on every change, or a hand-picked guess at what to run.
Multi-Platform TCM Export
One-click push to TestRail, Zephyr Scale, Qase, qTest, PractiTest, or Azure Test Plans — no copy-paste, no re-entry.
Manual copy-paste into each TCM platform; high risk of version inconsistency.
Integrations
Jira and ClickUp for stories and bug filing; Confluence, Figma and GitHub as story sources; GitHub, GitLab and Bitbucket repositories; Jenkins and GitHub Actions; Slack; Swagger and Postman import — all without custom code.
Custom API development required for each integration, with ongoing maintenance overhead.
Scalability
Thousands of test cases from one shared credit pool, while your QA team spends its time on review and exploration rather than typing.
Every new batch of test cases means more hours of writing and maintaining them by hand.
Consistency & Accuracy
Every run returns the same structured format — steps, expected results and priority — with no human fatigue.
Accuracy depends on individual tester skill; inconsistency rises sharply under deadline pressure.
Long-term Investment
Subscription-based; cost follows the credits you use, not the size of your QA team.
Recurring salaries, training, tooling, and benefits — total cost compounds significantly at scale.
02Time & Cost — Measurable Savings Breakdown
Faster Testing, Higher Quality, and Measurable ROI
With QAEverest, unlock the power of automation to generate comprehensive test cases in seconds — saving time, reducing costs, and ensuring maximum coverage far beyond what manual testing can achieve.
QAEverest savings comparison versus manual testing
Metric
Without QAEverest
With QAEverest
Your Saving
Test Cases Created
A tester produces ~20 test cases per day. Creating 2,400 test cases takes 120 working days (~6 months).
QAEverest drafts the same set from your stories in a fraction of that time, and your team’s effort moves to reviewing it.
Months of writing become review
Cost of Writing Tests
About 120 tester-days of writing for 2,400 cases — salary, overhead and tooling before a single test runs.
Credits from one shared team pool, used only for what you generate and run. The ROI Calculator works out your figure.
Run your own numbers
Test Case Accuracy
Prone to human error, missed edge cases, and inconsistency — especially under deadline pressure.
Each story gets positive, negative and edge-case scenarios in one consistent format, ready for review.
Fewer missed edge cases
Test Coverage
Coverage depends on tester experience; complex scenarios and corner cases are frequently missed.
Coverage-gap analysis names the requirements no test case covers yet, ranked so the biggest gaps come first.
Gaps named, not guessed
Scaling Up
Every rise in volume means more hours of writing and maintaining test cases by hand.
Volume grows within the same credit pool, and your QA team’s time goes to review, exploration and release decisions.
More coverage per tester
Time to First Automation
Setting up automation frameworks and writing the first scripts typically takes 2–4 weeks of engineering time.
Test cases go straight into a UI, API or mobile suite and run with no framework to build first.
Hours, not weeks
Test Maintenance
Each UI change breaks locators that someone has to find and fix by hand, run after run.
A moved element is found again and its locator updated; a broken step gets a proposed fix that a person accepts.
Fewer broken runs to chase
03QAEverest vs Other AI Testing Tools
QAEverest: Outperforming Other AI Testing Tools
When selecting an AI testing tool, evaluate depth — not just marketing claims. Here is a comprehensive, feature-by-feature breakdown of where QAEverest leads.
QAEverest AI testing tool compared to other AI testing tools
Generic output; usually functional only; rarely supports BDD.
Story Refinement
AI-powered requirement review, missing-scenario detection, and image/document upload support.
Not available in most tools.
Import Existing Tests
Rebuilds a repository of Playwright, Cypress, Selenium, pytest, JUnit or Cucumber tests, or a browser recording, as readable test cases and suites.
Rarely offered; existing tests are left behind or rewritten by hand.
API Automation (Built-in)
Postman and Swagger import; chained requests that pass values on; field-by-field response checks; read-only database checks against PostgreSQL, MySQL/MariaDB or MongoDB.
External framework required (Postman, RestAssured); no built-in engine.
UI Automation (Built-in)
Self-healing locators; Shadow DOM, SVG and iframe support; parallel runs; localization testing; video recording; cross-browser; CI/CD integration; detailed dashboards.
Not available; requires separate Selenium or Playwright setup.
Mobile Automation
Android and iOS apps through Appium, on real handsets or BrowserStack, Sauce Labs and LambdaTest, with scheduled runs.
Separate tooling required (Appium, Espresso).
Check Strength
Changes each passed check’s expected value and judges it again, so checks that could never fail are found before they let a bug through.
Not offered; a green result is taken on trust.
Pull Request Test Selection
Reads each GitHub, GitLab or Bitbucket pull request, scores its risk, picks the tests worth running and reports them as a commit-status check.
Rarely offered; the whole suite runs on every change.
Autonomous Exploratory Testing
Crawls your app from a URL and a login, maps every page, runs realistic flows, drafts a bug per failure and compares each crawl with the last.
Rarely offered, or limited to a single page.
AI Agent & LLM Testing
Tests your own chatbot or agent through its HTTP endpoint with factual, refusal, tool-call, personal-data and red-team scenarios, with a release gate for CI.
Usually a separate product, if offered at all.
Time-Travel Replay
Frame-by-frame replay with console, network and page detail, and an AI root cause for a failed web UI step.
Not available.
Visual Regression Detection
Automatic per-step baselines with a highlighted diff, kept per browser, device and data row.
Not available.
Multi-Platform TCM Export
One-click push to TestRail, Zephyr Scale, Qase, qTest, PractiTest, and Azure Test Plans.
1–2 export formats at most; no direct TCM platform push.
Download Formats
Excel and CSV downloads, the six TCM pushes, and runnable Playwright, Selenium or Cypress code after a run.
Typically Excel or PDF only.
Integrations
Jira, ClickUp, Confluence, Figma, GitHub, GitLab, Bitbucket, Jenkins and Slack — no custom code required.
Very limited or entirely unavailable.
Collaboration
Shared organisation projects with roles; stakeholders answer story questions from an emailed link; earlier versions of updated test cases can be restored; every change to what a check expects is recorded.
Single-user only; no collaboration or version tracking.
Test Case Insights
Coverage gaps per requirement, missing-scenario detection, and a free Test Case Audit for duplicates and tests never automated.
Raw output only; no analytics, insights, or diagnostics.
Accuracy & Diagnostics
A check that could not be confirmed reads Not verified, never a plain pass; visual and domain-based interpretation; AI-powered failure root-cause.
Variable accuracy; no built-in diagnostics.
User-Friendliness
Low-code; intuitive UI designed for manual testers and non-technical users.
Steep learning curve; often requires developer setup and scripting knowledge.
Security
SAML single sign-on, five ready-made roles plus custom ones, an audit log, server-side tenant isolation, and recognisable secrets swapped for placeholders before a prompt reaches the AI model.
Security posture unclear or undocumented.
Quality Command Center
A ship-confidence score with a ship, caution or blocked verdict, the gates that blocked it, and a release-readiness PDF.
Not available.
AI Copilot Assistant
Natural-language interface: "Run my last failed suite" or "Show coverage gaps" — streamed live with structured answers, in the web app and in VS Code, Cursor and JetBrains.
Not available.
Figma Design Import
Paste a Figma file URL and it drafts a story and test cases from the screens’ fields, buttons and flows.
Not available.
04QAEverest vs General-Purpose AI (ChatGPT & LLMs)
QAEverest vs General-Purpose AI: Purpose-Built Beats Prompting
General AI assistants like ChatGPT, Claude, Gemini, and Copilot can draft test ideas — but they can’t run, track, integrate, or govern your testing. Here is what changes when QA is the product, not a prompt.
QAEverest AI testing platform compared to general-purpose AI assistants such as ChatGPT
Feature
QAEverest
General-Purpose AI
Purpose
Purpose-built QA platform tuned for software testing across functional, API, UI, mobile, performance & security.
General-purpose chatbot with no testing domain model, workflow, or guardrails.
Test Case Generation
Structured test cases with consistent IDs and format, positive, negative and edge coverage, and duplicates checked for — written from your stories, issues, designs, repositories or recordings.
Ad-hoc cases inside a chat; volume, structure, and quality vary with every prompt.
Project Context & Memory
Persists projects, stories, requirements, and run history across sessions.
Limited context window; loses project context between chats.
Test Execution & Automation
Actually runs API, web UI and mobile tests and reports results — not just suggestions.
Writes text or code snippets only; cannot execute tests or report outcomes.
Proof a Test Can Fail
Check strength changes each passed check and confirms it would catch a wrong answer.
No way to tell whether a generated check could ever fail.
Change Awareness
Reads each pull request’s diff and picks the tests worth running; on GitHub it also proposes edits for tests the change breaks.
Sees only what you paste in; deciding what to re-test is left to you.
Requirement Traceability (RTM)
Built-in requirement-to-test traceability and coverage gap analysis.
No traceability; cannot reliably map tests back to requirements.
Export & TCM Integration
Excel and CSV downloads, a direct push to TestRail, Zephyr, qTest, Qase, Azure Test Plans or PractiTest, and Playwright, Selenium or Cypress code.
Copy-paste from chat; manual reformatting; no TCM platform integration.
Tool Integrations
Native Jira, ClickUp, Confluence, Figma, GitHub, GitLab, Bitbucket and Slack; Swagger and Postman import — no custom code.
No native integrations; everything moved in and out by hand.
Accuracy & Consistency
Every run returns the same structured format, ready to review, export or automate.
Output drifts between runs; prone to hallucinated, duplicate, or incomplete cases.
Collaboration & Versioning
Shared organisation projects with roles, stakeholder review from an emailed link, and earlier versions of updated test cases kept to restore.
Single-user chat; no shared workspace or version control.
Dashboards & ROI Insights
Coverage analytics, quality scoring, Test Health, and engineer-hours-saved ROI dashboards.
No analytics, dashboards, or reporting of any kind.
Data Security & Governance
Recognisable secrets swapped for placeholders before a prompt reaches the AI model; SAML single sign-on, roles and an audit log for organisations.
Prompts may be retained or used for model training; data governance is often unclear.
Total Cost & Effort
Credit-based usage from one shared team pool, covering generation through execution and export.
Token costs plus heavy manual effort to assemble, format, and maintain a usable suite.