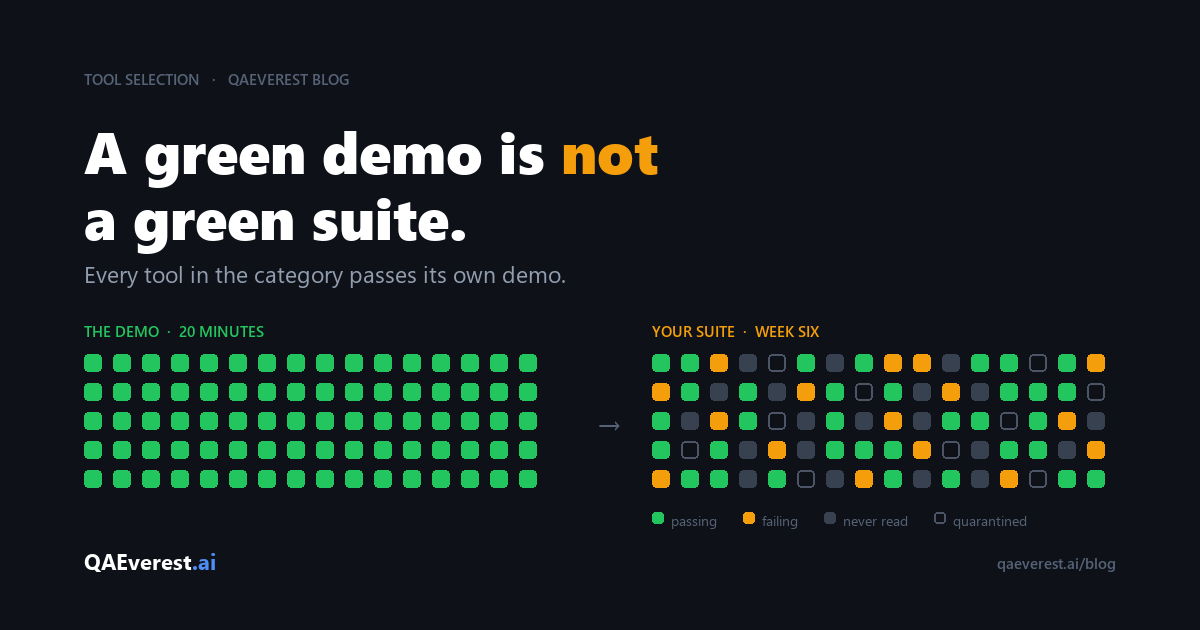
Three years ago the problem was that nothing worked. Now the problem is that everything demos. Twenty minutes, a clean sample app, a flow the vendor's engineer has run four hundred times — and it goes green. Every tool in the category can do that. Which means the demo, the thing your evaluation is built around, has almost no power to tell one tool from another. The market didn't get harder to buy from because the tools got worse. It got harder because they all look identical for the first twenty minutes, and they stop looking identical at around week six.
Why a demo cannot discriminate
A demo runs on a stable application, with pre-built flows, curated test data, and a driver who knows every quirk of both the product and the tool. Those four conditions are exactly the ones your team will never have. The three things that actually decide whether a tool survives in your team are invisible under demo conditions:
- What happens when the application changes, which is the entire maintenance bill.
- What a failure tells you before a human starts digging, which is the triage bill.
- Who on your team can still operate it in six months, which decides whether it becomes shelfware.
None of those can be shown on a stable app in twenty minutes. All of them can be tested, if you change what you ask for.
Know which kind of tool you are looking at
"AI testing tool" now covers five genuinely different products. Most disappointment comes from buying one kind while expecting another.
| What it actually is | Genuinely good at | Where it runs out |
|---|---|---|
| Record and replay | A first suite, fast, with no code | Brittle under redesign; recordings are hard to review or diff |
| Script generators | Authoring speed, familiar output your devs can read | The generated selectors are still hardcoded guesses, so maintenance is unchanged |
| IDE copilots | Unit and API tests, written where developers already work | Nobody ends up owning the end-to-end suite |
| Low-code builders | Non-coders authoring real flows | A ceiling, and an escape hatch that is code only developers can use |
| Runtime-resolution runners | Surviving UI change; richer failure triage | Real compute cost per run, and non-deterministic behaviour you have to audit |
Note the second row, because it is the most common expensive mistake. A tool that writes Playwright for you has moved work from authoring to review. It has not touched the maintenance curve at all, and maintenance is where suites die.
Five questions that separate them
Ask these of every vendor, in this order, and listen for the shape of the answer rather than the enthusiasm.
1. "Rename a CSS class in your demo app right now, then run it again." A weak answer talks about AI-powered locators. A strong one just does it, the run survives, and the report names the element it repaired. If a vendor will not let you break the app during the call, you have learned the most important thing about the tool.
2. "What does a failure tell me before I open the video?" A screenshot and a stack trace mean a human still does the whole diagnosis. Look for a run that states up front whether this was a test failure or an application failure. That single distinction is most of your triage cost.
3. "Who on my team maintains this in six months, and what exactly do they edit?" Every tool has one artifact its whole model rests on: a recording, a script, a test case, a config. Ask to see it. If the honest answer is "your automation engineers edit generated code," you have bought authoring speed, not leverage.
4. "What does the tool do with a flaky test?" If the answer is retries, the tool is hiding the mechanism and letting it grow. Ask whether it measures per-test pass rate on known-good builds, and whether it can quarantine a bad test with an owner rather than a retry count.
5. "What is the bill, and how do I leave?" Get cost modelled against your real volume, including reruns and retries, not per-seat pricing on a slide. Then ask what export looks like and what is lost in it. A vendor who answers the exit question calmly is telling you something about the next two years.
Replace the demo with four days
The best evaluation costs you less than a week and cannot be gamed.
- Day one: bring your ugliest flow. Not the login. The one with three environments, a PDF download, and a flaky third-party redirect. The tool that handles your worst path handles your median path.
- Day two: break the application on purpose. Rename a class, move a field into a modal, add a cookie banner. Watch what fails, what repairs, and whether the report tells you which happened.
- Day three: hand it to the person who did not choose it. A manual tester on the team, with no walkthrough. If they cannot author and read a run unaided, adoption will stall no matter what the pilot proves.
- Day four: read three failure reports end to end. Time yourself. That number, multiplied by your red builds per month, is the actual return on the purchase.
The question underneath all of it
Every tool in this market is optimising something. Some optimise how fast the first hundred tests get written. Some optimise how little code you have to see. A few optimise what happens on the Tuesday the application changes underneath you. Only one of those three is a recurring cost, and it is the one no demo will ever show you.
Bring your worst flow, break it deliberately, and buy the tool that tells you the truth about what just happened.


